
Computer vision is transforming industries by enabling machines to interpret images, recognize objects, identify patterns, and make data-driven decisions. However, the accuracy of these AI systems depends heavily on the quality of their training data. This is where image annotation plays a critical role. By adding meaningful labels, boundaries, categories, and other contextual information to images, annotation helps machine learning models understand what they see and how different visual elements relate to one another.
Choosing the right annotation method is equally important. A technique suitable for detecting products in retail images may not be sufficient for identifying pedestrians in autonomous driving scenarios or locating abnormalities in medical scans. Selecting the wrong approach can increase annotation costs, introduce inconsistencies, and limit model performance.
For AI teams, understanding the strengths and limitations of different image annotation techniques is essential to building reliable computer vision systems. Annotera helps businesses prepare high-quality visual datasets through structured annotation workflows tailored to specific AI applications.
Why Choosing the Right Image Annotation Technique Matters
Every computer vision application has distinct data requirements. Some models need to identify the presence of an object, while others must determine its exact location, outline, or relationship with surrounding objects.
The right annotation technique helps organizations:
Improve model accuracy by providing relevant and consistent training labels.
Reduce ambiguity in complex images through precise labeling guidelines.
Optimize annotation time and costs by avoiding unnecessarily detailed labeling.
Support scalability across large datasets and evolving AI projects.
Improve model generalization across different environments, lighting conditions, and object variations.
An effective annotation strategy begins with a clear understanding of the model's intended task, the complexity of the images, and the level of precision required.
6 Essential Image Annotation Techniques for Different AI Applications
1. Bounding Box Annotation for Object Detection
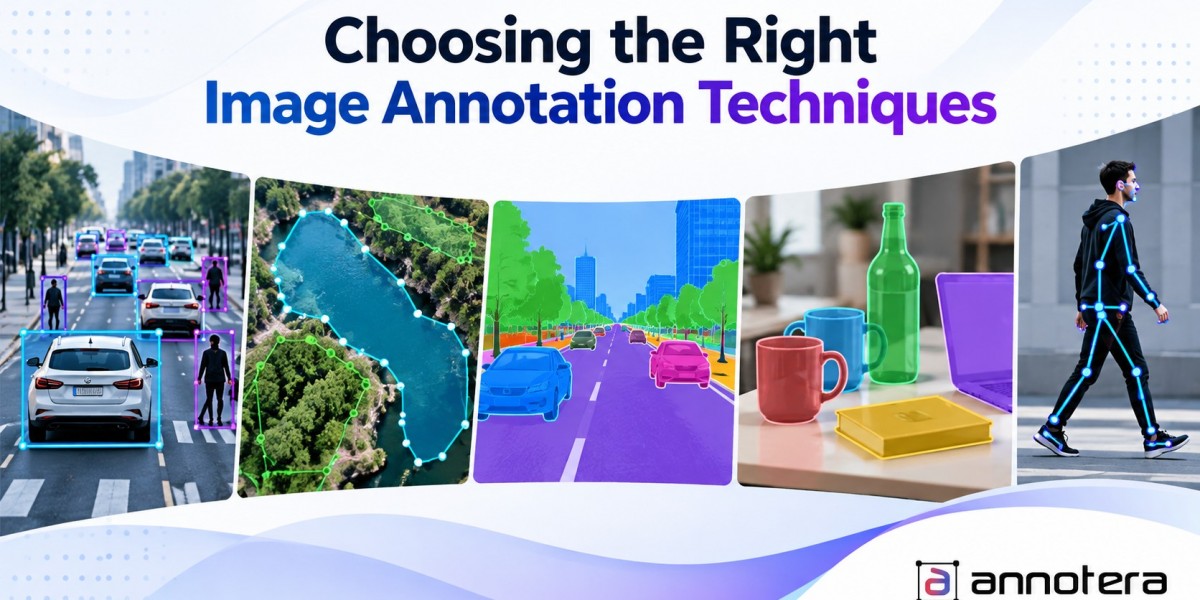
Bounding box annotation involves drawing rectangular boxes around objects and assigning category labels. It is one of the most widely used techniques for training object detection models.
Best applications: Retail inventory monitoring, traffic surveillance, warehouse automation, and autonomous driving.
For example, a retail AI system can use bounding boxes to detect products on shelves, while an autonomous vehicle model can identify cars, pedestrians, and traffic signs. This technique is relatively efficient for large datasets because annotators can label multiple objects without tracing their exact outlines.
However, bounding boxes include some background pixels around objects. They may be insufficient when applications require precise object boundaries or detailed shape information.
2. Polygon Annotation for Irregular Object Shapes
Polygon annotation uses multiple connected points to trace an object's outline. Unlike rectangular bounding boxes, polygons capture irregular shapes more accurately.
Best applications: Agriculture, aerial imagery, industrial inspection, and environmental monitoring.
In agriculture, polygons can outline crop patches, leaves, or damaged areas. For satellite imagery, they can identify buildings, roads, and land-use regions with greater boundary precision.
Polygon annotation is particularly useful when object shape influences model performance. However, it requires more time and careful quality control, especially when objects have complex boundaries or overlap with other elements.
3. Semantic Segmentation for Pixel-Level Classification
Semantic segmentation assigns a class label to every pixel in an image. This allows AI models to distinguish between regions belonging to different categories, rather than simply locating objects.
Best applications: Autonomous vehicles, medical imaging, robotics, and satellite image analysis.
For autonomous driving, semantic segmentation can classify roads, sidewalks, buildings, vehicles, and vegetation at the pixel level. In medical imaging, it can help identify anatomical structures or regions of interest in scans, subject to appropriate clinical validation.
This technique is valuable when precise scene understanding is necessary. However, annotation can be resource-intensive because large image areas require detailed labeling and consistent class boundaries.
4. Instance Segmentation for Identifying Individual Objects
Instance segmentation combines object detection with pixel-level segmentation. It identifies individual objects and outlines each separately, even when several objects belong to the same category.
Best applications: Warehouse robotics, autonomous driving, manufacturing, and automated counting systems.
For example, a robotic picking system may need to distinguish individual products piled together. Instance segmentation allows the model to identify each item's precise outline, supporting object separation and manipulation.
Although this approach provides richer visual information than bounding boxes, it generally requires more annotation effort and stronger quality assurance.
5. Keypoint Annotation for Pose and Landmark Detection
Keypoint annotation marks specific points on an object, such as joints on a human body, facial landmarks, or important mechanical reference points.
Best applications: Human pose estimation, gesture recognition, facial analysis, sports analytics, and robotic manipulation.
In robotics, keypoints can represent the grasp points or critical landmarks of an object. In human pose estimation, they can identify shoulders, elbows, knees, and other body joints.
The technique is useful when the relationships between points matter more than the object's complete outline. Consistent landmark definitions and clear visibility rules are essential for reliable datasets.
6. Image Classification for Category Recognition
Image classification assigns one or more labels to an entire image rather than marking individual objects or pixels.
Best applications: Product categorization, defect screening, document image classification, and agricultural disease identification.
For instance, a manufacturing model can classify an image as containing a defective or non-defective component. An agricultural AI system may classify leaf images by disease category.
Classification is generally faster and less expensive than detailed spatial annotation. However, it does not reveal where an object or defect appears within the image, making it unsuitable when precise localization is required.
How to Select the Right Annotation Technique
AI teams should evaluate annotation methods against five practical considerations:
Model objective: Determine whether the system needs classification, detection, segmentation, or landmark recognition.
Required precision: Choose pixel-level techniques when boundaries matter; use bounding boxes when approximate object localization is sufficient.
Dataset complexity: Consider object overlap, image resolution, background variation, and visibility.
Budget and scalability: Balance annotation detail against project timelines, dataset size, and available resources.
Quality requirements: Establish labeling guidelines, review processes, and measurable acceptance criteria before scaling production.
Combining techniques can also be beneficial. A dataset may use bounding boxes for general object detection and segmentation masks for selected objects that require finer-grained understanding.
Why Partner with an Image Annotation Company?
Managing image annotation internally can become challenging as dataset volumes, labeling complexity, and model requirements increase. An experienced image annotation company can provide trained annotators, standardized workflows, quality assurance, and scalable production capacity.
By leveraging image annotation outsourcing services, businesses can reduce the operational burden of dataset preparation while allowing internal AI teams to focus on model development and evaluation. The right partner should support project-specific annotation formats, transparent quality metrics, data security requirements, and flexible scaling.
Annotera supports AI and machine learning teams with image annotation workflows designed around application requirements. From object detection and classification to segmentation and specialized visual labeling, a structured approach helps organizations build more consistent, useful training datasets.
Conclusion
Selecting the right image annotation technique is a foundational decision in computer vision development. Bounding boxes offer efficient object localization, polygons capture irregular boundaries, semantic segmentation enables pixel-level scene understanding, instance segmentation separates individual objects, keypoints support landmark detection, and image classification enables category recognition.
The best choice depends on the model's objective, required precision, dataset complexity, and operational constraints. By aligning annotation methods with real-world AI requirements and implementing rigorous quality checks, organizations can improve training data reliability and support stronger model performance.
Ready to strengthen your computer vision datasets? Partner with Annotera to explore image annotation solutions tailored to your AI use cases. Contact our team to discuss your dataset requirements and build a scalable annotation strategy.